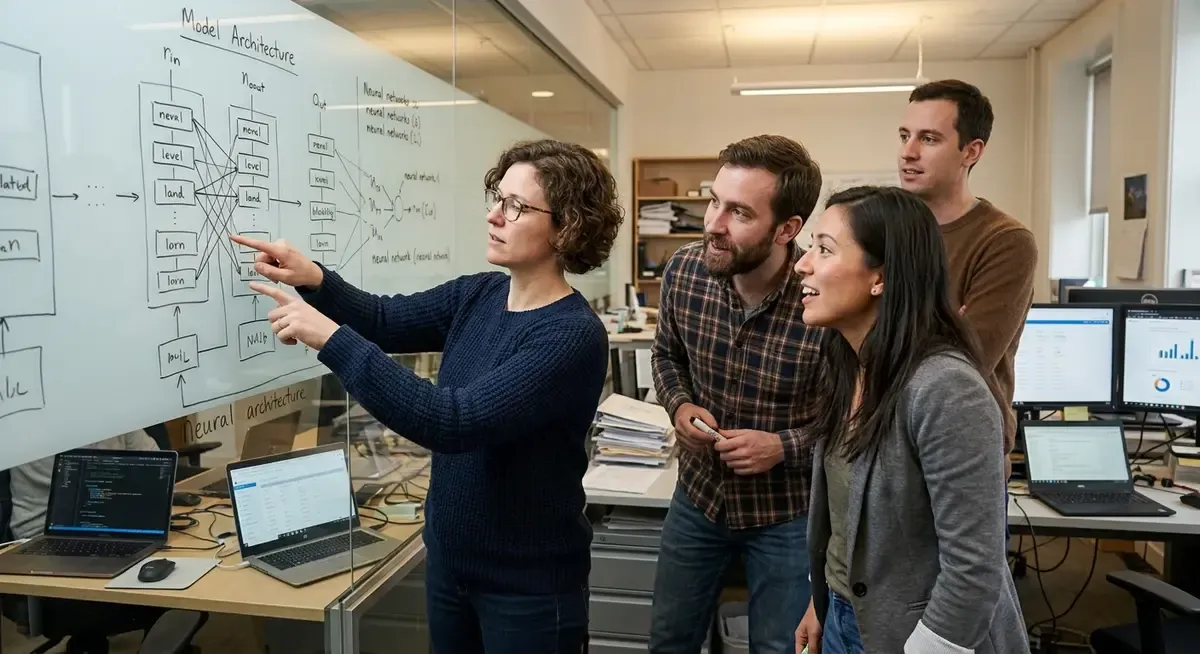
Editorial illustration for Google Research Releases RRSI: Self-Improving AI Agents With Cost, Pruning Rules
Google Research Releases RRSI: Self-Improving AI Agents...
Google Cloud AI Research, working with teams at UNC-Chapel Hill, Stanford and Washington University in St. Louis, has open-sourced a framework called RRSI, short for Regularized Recursive Self-Improvement. The idea: let an AI agent rewrite its own operating harness, meaning prompts, tools, memory, control flow and sub-agents, without touching the underlying model weights.
That distinction matters. Most self-improving agent setups run into the same wall. They optimize against a fixed set of evaluation tasks, and the editing loop starts memorizing those tasks rather than getting genuinely better.
Scores on the evolve set climb while performance on anything new stalls or drops.
RRSI is built specifically to close that gap. Rather than leaving the harness free to mutate however it wants, the framework puts constraints on the improvement process itself, on the theory that regulating the search is more useful than regulating the output. The code ships under an Apache 2.0 license, runs on Python 3.10 or later, and works with any LiteLLM model string, though the defaults point to Claude Opus 4.8 on Vertex AI. Google's researchers identify three specific ways these loops go wrong, and RRSI targets each one directly.
Google Cloud AI Research, with UNC-Chapel Hill, Stanford and Washington University in St. Louis, has released RRSI (Regularized Recursive Self-Improvement). It lets an LLM agent rewrite its own harness: prompts, tools, memory, control flow and sub-agents.
Why this matters
For teams building agents, RRSI is a useful reframe: the harness, not the weights, is where most of the cheap, deployable gains are hiding right now. That's worth our attention because it lowers the barrier to iteration. You don't need GPU budget for fine-tuning to squeeze more reliability out of an agent, you need discipline about what edits earn their keep.
The L0/L1/L2 framing (edit budget, pruning, cost rule) is a genuinely clean way to stop self-improving agents from just bloating their own prompts and tool lists until they overfit to a benchmark. Apache 2.0 licensing and LiteLLM support mean this isn't a paper you admire and shelve, it's something a research team could plug into an existing agent stack this week.
We'd stay skeptical about how well "gains hold" claims generalize past Google's test suite. Regularizing a self-editing loop is smart engineering, but self-improvement systems have a track record of looking robust until someone throws a harder benchmark at them. Worth watching whether independent teams reproduce the no-overfitting result outside Google's own evals.
Related Reading
Browse all Google news → Research & Benchmarks
Microsoft AI Chief: "If It Isn't Safe We Shouldn't Build It
 Research & Benchmarks
Google's FACTS benchmark shows 70% factuality ceiling across four tests
 Research & Benchmarks
Nvidia's DLSS 4.5 beta adds 6x Multi Frame Generation for RTX 50 GPUs
 Related Topic
NVIDIA and Google Cloud let developers scale AI from prototype to production
Market Trends
 Related Topic
Google tests visual 'magazine-style' UI for Gemini 3 Pro users
LLMs & Generative AI
 From Archives
AI Agents Assisted With Lab Grunt Work, Not Discovery
 From Archives
OpenAI Faces Scrutiny Over Hiring Ethics Amid Mathematician Criticism
 From Archives
Google Details Four Frameworks for AI Co-Directed Video Generation
 From Archives
Google Tests Direct Purchases Through Gemini AI on India's Flipkart
LLMs & Generative AI
Further Reading
- RRSI: Regularized Recursive Self-Improvement of Agent Harnesses - arXiv
- google-research/rrsi - GitHub
- Google Research Open-Sources RRSI: AI Agents That Improve Their Own Harness Without Overfitting - MarkTechPost
- Google researchers built a fix for AI agents that cheat their own tests - AI Insiders
- Google's RRSI curbs overfitting in self-improving AI agent harnesses - Glonce
