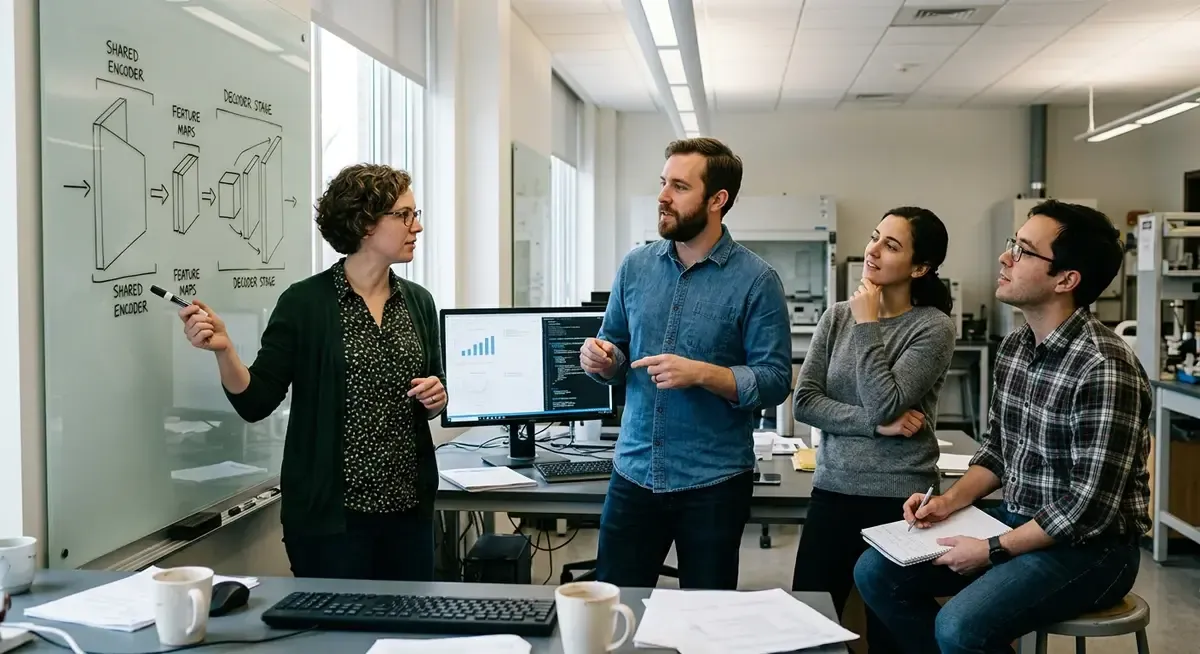
Editorial illustration for EmbeddingGemma 2 Unifies Text, Code, Images, Video and Audio
EmbeddingGemma 2: Unified Multimodal Search Model
EmbeddingGemma 2 Unifies Text, Code, Images, Video and Audio
Google released EmbeddingGemma 2 on October 6, 2026, under an Apache 2.0 license, and it solves a problem anyone building multimodal search has run into: text, images, video, audio and code don't live in the same vector space by default. Built on Gemma 4 and sized under 1B parameters, the model maps all five content types into one 768-dimensional space using a single backbone with modality-specific front-end encoders bolted on.
That architecture choice matters because the standard workaround, running separate models per content type and merging results afterward, creates mismatched score ranges and separate indexes that don't talk to each other well. A photo and a paragraph end up with no common ground for comparison. EmbeddingGemma 2 ships as one checkpoint with four loadable configurations, letting developers choose at load time which encoders to activate without paying memory cost for the ones they skip.
This piece walks through how that single-space design works in practice, what the benchmark numbers show, and includes runnable scripts so the claims can be checked rather than taken on faith.
The usual way to search across mixed content is to run one model per content type and stitch the results together afterwards. That means separate indexes, separate score ranges, and no reliable way to compare a photo against a paragraph. EmbeddingGemma 2 removes that problem by sending every content type through one backbone.
Why this matters
For teams building search or retrieval systems across mixed media, EmbeddingGemma 2 removes a real engineering tax. Running separate models per content type means separate indexes, mismatched score ranges, and brittle glue code to reconcile them. A single 768-dimensional space with one set of weights changes the calculus: you load only the encoders you need, text-only deployments skip the vision and audio stacks entirely, and nothing sits idle in RAM.
That modularity matters more than the headline number of modalities. The ability to embed a query with the 270M text configuration and match it against documents encoded with the full model, without retraining or reindexing, is the kind of detail that decides whether a lab actually adopts this versus just benchmarking it once and moving on. We'd want to see how it holds up on noisy, real-world video and audio rather than curated benchmark sets before treating this as settled.
Apache 2.0 licensing and sub-1B size make it cheap to try, which is exactly the point: this is infrastructure, not a flagship model, and its value will show up in fewer moving parts rather than leaderboard wins.
Related Reading
 Research & Benchmarks
Microsoft AI Chief: "If It Isn't Safe We Shouldn't Build It
 Research & Benchmarks
Google's FACTS benchmark shows 70% factuality ceiling across four tests
 Research & Benchmarks
Nvidia's DLSS 4.5 beta adds 6x Multi Frame Generation for RTX 50 GPUs
 From Archives
OpenAI Fires Three Safety Researchers for Policy Violations
 From Archives
NVIDIA's Astra AI Generates Code for SimReady Robot Assets
Common Questions Answered
How does EmbeddingGemma 2 solve the multimodal search problem that traditional approaches face?
EmbeddingGemma 2 maps all five content types (text, images, video, audio, and code) into a single 768-dimensional vector space using one backbone with modality-specific front-end encoders. This eliminates the traditional workaround of running separate models per content type, which required separate indexes, mismatched score ranges, and complex glue code to reconcile results across different media formats.
What are the technical specifications and architecture of EmbeddingGemma 2?
EmbeddingGemma 2 is built on Gemma 4 with under 1B parameters and uses a single backbone architecture with modality-specific front-end encoders for handling different content types. The model projects all content into a unified 768-dimensional embedding space, enabling direct comparison and search across text, code, images, video, and audio without separate processing pipelines.
What license was EmbeddingGemma 2 released under and when did it become available?
Google released EmbeddingGemma 2 on October 6, 2026, under an Apache 2.0 license, making it freely available for open-source use. This permissive licensing enables developers and teams to integrate the multimodal embedding model into their search and retrieval systems without commercial restrictions.
What engineering benefits does EmbeddingGemma 2 provide for teams building mixed-media search systems?
EmbeddingGemma 2 reduces engineering complexity by eliminating the need for separate models, indexes, and reconciliation code that traditional multimodal search requires. Teams can now load only the encoders they need for their specific use case, with text-only deployments able to skip vision and audio stacks entirely, resulting in more efficient resource utilization and reduced RAM overhead.
What problem does the unified vector space in EmbeddingGemma 2 solve compared to running separate models per content type?
The unified 768-dimensional vector space enables reliable comparison between different content types, such as comparing a photo directly against a paragraph. In contrast, separate models per content type create mismatched score ranges and require brittle glue code to stitch results together, making cross-media relevance scoring unreliable and maintenance-heavy.
Further Reading
- Google expands EmbeddingGemma beyond text to images, audio and video - SiliconANGLE
- EmbeddingGemma 2: an open, lightweight multimodal embedding model - Google Blog
- EmbeddingGemma 2: The Developer Guide - Google Developers Blog
- Bring multimodal semantic search to the edge with EmbeddingGemma 2 - Google AI Edge Blog
- Multimodal Embeddings with EmbeddingGemma 2 - Google AI for Developers
