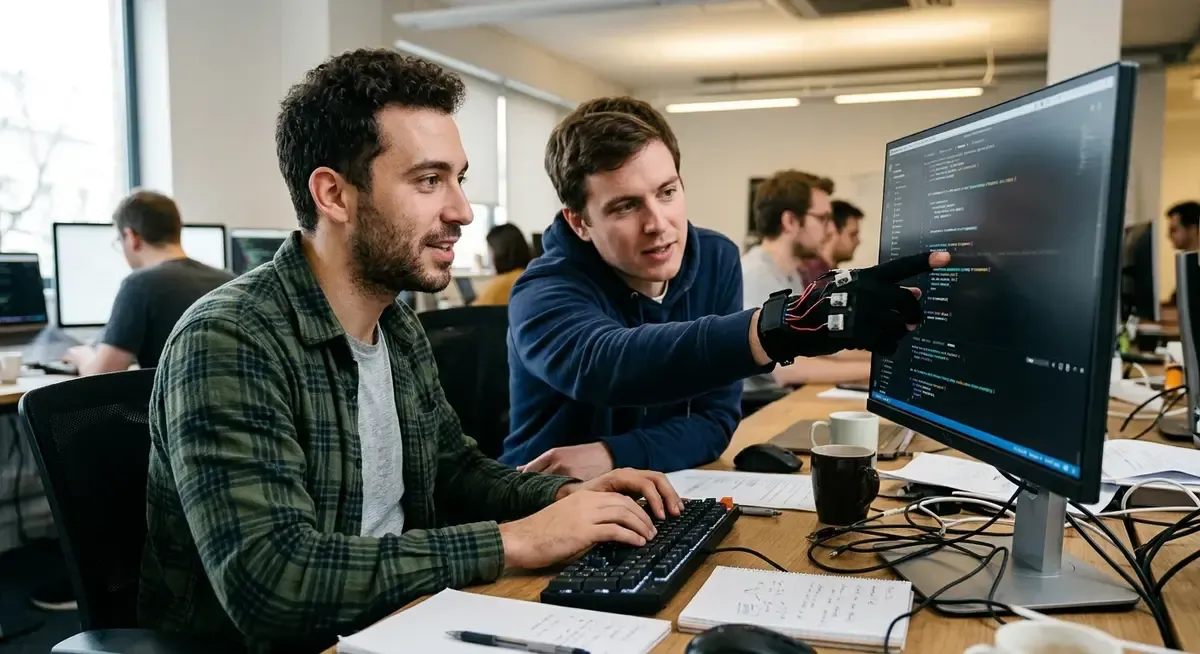
Editorial illustration for Reward AI's OM-1 Robot Policy Trained Solely on Human Wearable Data
OM-1 Robot Learns Manipulation From Human Wearables
Reward AI's OM-1 Robot Policy Trained Solely on Human Wearable Data
Reward AI, the robotics startup behind DexCap, HumanPlus, and ALOHA, has released OM-1, its Omnibody Model 1. The policy learns manipulation entirely from a person wearing a sensorized glove, then transfers that behavior to industrial arms and humanoids running at human speed. No teleoperation data went into training.
No on-robot data either. That's the detail that separates OM-1 from most robot foundation models, which typically depend on one or both.
OM-1 isn't something outside developers can touch yet. Reward AI hasn't released weights, code, a dataset, or an API, so it stays an in-house policy for now, not a deployable tool.
The bigger claim is about method. Reward AI argues that stacking more teleoperated or robot-specific data, or throwing more compute at the problem, won't produce human-level manipulation on its own. The company points to Anderson's "More Is Different" to make that case, and builds its pipeline around a single idea: capture, learning, and control as one system, so today's human demonstrations can train robot bodies that haven't been built yet.
Reward AI, a robotics startup whose team’s prior work includes DexCap, HumanPlus, and ALOHA, has released OM-1, short for Omnibody Model 1. OM-1 is a general-purpose manipulation policy that learns from humans wearing a sensorized glove, then runs on industrial arms and humanoids at human speed. The key findings that stands out: no teleoperation data and no on-robot data go into training.
Why this matters
OM-1 is a bet that the bottleneck in robot learning isn't compute or model size, it's data collection. Teleoperation rigs and on-robot demonstrations are slow and expensive to scale, which is why most manipulation policies still choke on anything outside their training distribution. Reward AI's team, coming off DexCap, HumanPlus, and ALOHA, is betting a sensorized glove can strip out the robot entirely and just capture how a person's hand actually behaves at conveyor-belt speed.
That's a real claim worth scrutinizing, not celebrating yet. The company itself says OM-1 isn't deployable, so the "human speed" framing is aspirational until we see it running on an actual sorting line with error rates published. For founders building manipulation stacks, the interesting part is the data interface, not the model.
If wearable capture genuinely transfers across arms and humanoids without teleoperation, that changes the economics of who can afford to train these systems. Worth watching for benchmarks against teleoperated baselines, not just demo videos.
Related Reading
 Open Source
D&B rebuilds 642 million‑business database after AI agents hit limits
 Open Source
OpenAI's GPT Transcribe Cuts Error Rate to 3.31%, Improving on GPT-4o
 Open Source
Study: 6.7% of Deepfake Requests on Hugging Face Targeted Children
 From Archives
DeepSeek-V4.1-Flash Cuts Memory Use With FP4 KV Caching
 From Archives
AWS Launches Pizza Bot, an Open Source Inbox for AI Agents
Common Questions Answered
What makes OM-1's training approach different from other robot foundation models?
OM-1 is trained exclusively on human wearable data from a sensorized glove, with no teleoperation data or on-robot data included in the training process. This approach sets it apart from most robot foundation models, which typically depend on one or both of these data sources to learn manipulation skills.
How does OM-1 transfer learned behaviors from human wearable data to robots?
OM-1 learns manipulation skills from a person wearing a sensorized glove, then transfers that behavior directly to industrial arms and humanoids, which run at human speed. This transfer occurs without requiring any teleoperation rigs or on-robot demonstrations during the training phase.
What problem does Reward AI believe OM-1 solves in robot learning?
Reward AI's team identifies data collection as the primary bottleneck in robot learning, not compute or model size. By using a sensorized glove to capture human hand behavior instead of relying on expensive teleoperation rigs and on-robot demonstrations, OM-1 enables faster and more scalable training for manipulation policies.
What is the connection between OM-1 and Reward AI's previous projects?
Reward AI's team previously developed DexCap, HumanPlus, and ALOHA, which informed their approach to creating OM-1. The experience from these prior projects helped shape OM-1's strategy of using sensorized glove data to train general-purpose manipulation policies without traditional teleoperation or on-robot data.
Further Reading
- Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data - MarkTechPost
- Reward AI launches OM-1 to run one policy across robot bodies - RuntimeWire
- Papers with Code - Latest NLP Research - Papers with Code
- Hugging Face Daily Papers - Hugging Face
- ArXiv CS.CL (Computation and Language) - ArXiv
